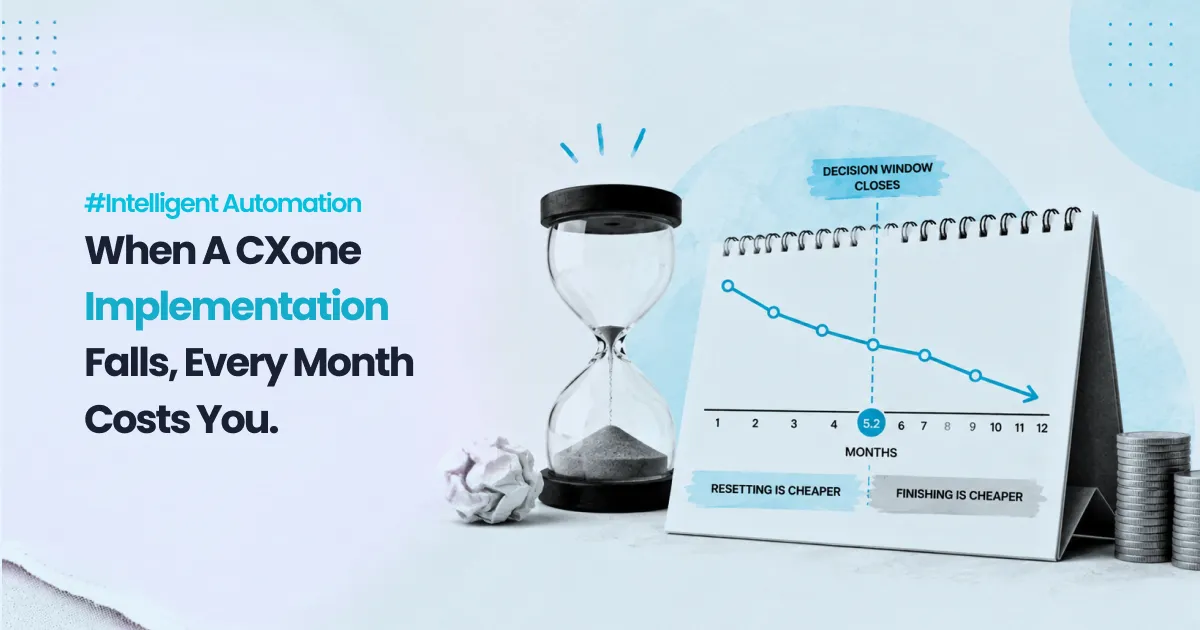
A prospect asked us this on a call last year, about nine months into a build with somebody else: “At what point do we stop trying to fix this and start again?”
It is the right question and almost nobody asks it out loud. What gets asked instead is whether the implementation is going badly, which is unanswerable, because every implementation is going badly somewhere. The useful question is narrower and has an actual answer. There is a last month in which starting over is cheaper than carrying on. After that month, the arithmetic flips permanently, and the flip has nothing to do with how much has already been spent.
This post works out where that month falls and what moves it. NICE CXone is the platform in the examples, but the structure holds for any contact-centre platform programme where configuration decisions compound.
Failure does not arrive on a date
The reason the question gets asked at month nine instead of month three is that platform implementations do not fail in a way that produces a notification.
Consider what a public audit found when it looked at exactly this. The US Government Accountability Office examined the Internal Revenue Service’s technology modernisation programmes and reported that the agency was meeting most of its quarterly targets. Then it looked underneath the reporting. One key investment “was within schedule estimates for 2019 and 2020” while repeated changes to the overall programme plan “led to a 9-year milestone delay–from 2014 to 2023.” The quarterly reports, , “did not show this lengthy delay because they do not include programs’ historical cost and schedule goals.”
Nine years of slippage, invisible in a status report that was accurate every time it was filed. Nobody falsified anything. The reporting measured performance against the current plan, and the current plan had moved.
This is the mechanism that makes a CXone implementation feel fine until it obviously is not. Your weekly report says configuration is 70% complete against the plan. It does not say that the plan was rewritten in month four because the original routing design could not accommodate the third business unit, and it will not say that the workaround adopted in month four is the thing that will require rebuilding in month eleven.
The same pattern shows up on the UK side, in a programme that is a much closer analogue to a contact-centre replacement. The National Audit Office reviewed National Savings and Investments — an organisation with, in its own reporting, “some 25 million customers, who have collectively invested over £240 billion” — as it replaced a twenty-five-year incumbent supplier with a multi-supplier model. The programme was rated red in the Infrastructure and Projects Authority’s annual reports for two consecutive years, red meaning “successful delivery of the project appears to be unachievable.” The NAO’s conclusion is worth reading slowly: NS&I “underestimated the scale of this challenge and overestimated its ability to deliver the Programme, despite warning signs about its lack of skills and capability and the complexity of disentangling a highly integrated IT system.” And: “The Programme was not sufficiently thought through before key decisions were made, which led to significant cost and time increases.” Those are , published November 2025.
“Not sufficiently thought through before key decisions were made” is the whole failure mode in nine words. The decisions were made early. The consequences arrived late. Nothing in between reported a problem.
The five things that are actually wrong
Before pricing the decision, name what is being decided about. In our experience these are the design faults that surface late and cost the most to unwind, and none of them is a technology defect.
Each of these is cheap to change during design and expensive to change once it is load-bearing. That asymmetry is the entire basis of the calculation that follows.
Pricing the window
Here is the arithmetic that answers the prospect’s question. The figures are illustrative and chosen to be legible, not drawn from a client engagement; the structure is what transfers, and you should substitute your own numbers.
A twelve-month programme to go-live. Build spend of €60,000 a month, covering partner fees and internal time. At some month, someone establishes that a material design decision was wrong — one of the five above. Thirty per cent of the configuration built so far sits on that decision.
Two forward paths.
Finish on the flawed design, then fix it live. You spend the remaining build months as planned, and after go-live you rebuild the affected configuration at 1.8 times what it cost to build the first time, because it is now in production, integrated, and being used. Add four months of degraded operation before the fix lands, costing €26,000 a month in rework, escalations and abandoned contacts.
Stop, re-decide, rebuild. A redesign engagement of €150,000 to diagnose and re-decide. Two months of calendar time consumed by that engagement, plus however long it takes to redo the affected work. Go-live slips by the total, and delayed benefit costs €70,000 a month.
Notice what is not in either path: the money already spent. It appears in neither expression, because it cannot be recovered by either choice. This is not a rhetorical point about sunk cost discipline. It is a structural feature of the comparison, and it means the answer does not depend on how deep you are — only on how much of the build rests on the bad decision and what the two penalty rates are.
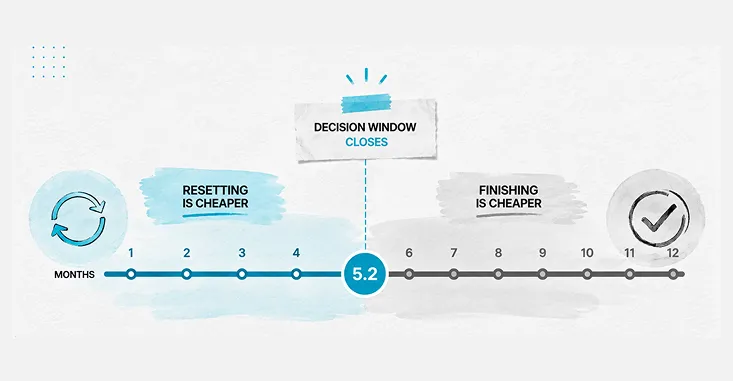
Run it month by month, and the crossover lands at month 5.2.
- Decide at month 3: resetting costs €947,000 against €1,032,800 to carry on. Resetting saves €85,800.
- Decide at month 5: €905,000 against €912,800. Resetting saves €7,800. The window is nearly shut.
- Decide at month 5.2: both paths cost €900,800. Exactly indifferent.
- Decide at month 6: resetting now costs €31,200 more than finishing.
- Decide at month 8: resetting costs €109,200 more.
- Decide at month 12: €265,200 more.
The window is open for five months of a twelve-month programme. After that, the correct answer to “should we start again?” is no — not because the design is acceptable, but because you will now pay less by launching something you know is wrong and fixing it in production. That is a genuinely unpleasant conclusion and it is what the numbers say.
There is a harder result underneath it. Rewrite the crossover as a function of how much configuration sits on the flawed decision, and it has a ceiling. As that share rises towards everything, the window converges on 9.97 months and never passes it. Even if the entire build were compromised, the window would close at 8.54 months. There is no version of this programme in which a decision taken in month ten is better made by starting over. The window is bounded by the ratio of the live-fix premium to the cost of delay, not by the size of the problem.
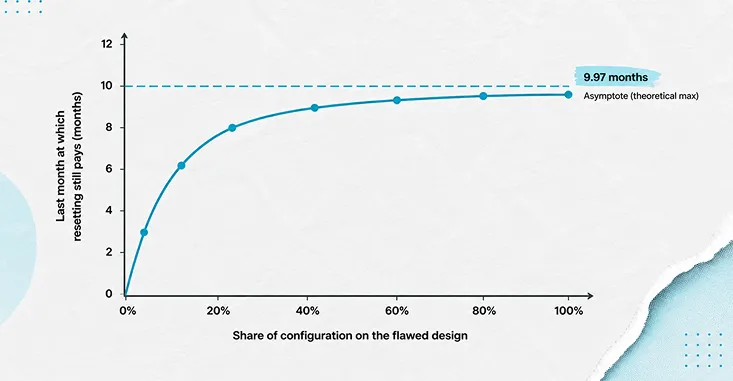
What moves the window, and the case where it never opens
Four sensitivities, each solved for the value that puts the crossover at a stated month.
And the case where none of this applies. Change one number — the flawed share drops from 30% to 12% — and the model produces a losing row. Resetting is more expensive at every month from zero to twelve. The cheapest moment to reset is worse than carrying on by €30,480, and the penalty grows from there. If you had run this calculation on that programme and reset anyway because it felt decisive, you would have destroyed thirty thousand euros to feel better. The window is not always open, and a method that always recommends action is not a method.
The number your steering committee is not looking at
Programme reporting tracks budget consumed. Almost nothing tracks window consumed, and the two run at different speeds.
At month five of this programme you have spent 41.67% of the planned build budget. You have used 96.15% of the decision window. The window burns 2.31 times faster than the budget.
That gap is why the prospect’s question arrived in month nine. By any measure on the status report, a programme at month five is comfortably mid-flight with more than half its money unspent. By the only measure that governs whether a design fault is still correctable, it is finished. Put both percentages side by side in the monthly pack. If the second one is not on the page, the first one is telling your steering committee that there is time when there is not.
The clause that keeps the option alive
None of this arithmetic matters if you cannot actually execute the reset, and contractually most buyers cannot. The reset path assumes you can stop, take your configuration and your knowledge, and continue with someone else. If your agreement does not say how that happens, the reset option is priced into your model but absent from your contract.
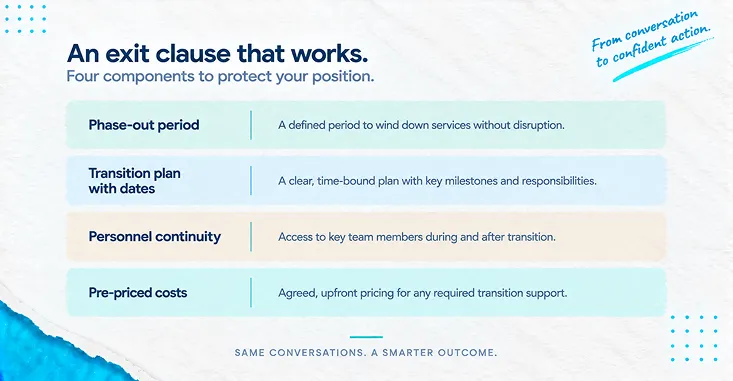
Public procurement solved this a long time ago, and the language is worth borrowing. US federal contracts carry a standard continuity-of-services clause. Under , the contractor “recognizes that the services under this contract are vital to the Government and must be continued without interruption” and agrees to furnish phase-in training and to “exercise its best efforts and cooperation to effect an orderly and efficient transition to a successor.” On written notice it must furnish phase-out services for up to ninety days after expiry and negotiate a transition plan in good faith. The plan “shall specify a training program and a date for transferring responsibilities for each division of work described in the plan.” It must allow as many personnel as practicable to stay on the job, disclose necessary personnel records, and permit the successor to conduct on-site interviews. And it gets reimbursed for reasonable phase-in and phase-out costs plus a pro-rata fee — the obligation is paid for, not extracted.
Four things to lift into your own statement of work:
- A phase-out period with a number on it. Ninety days is the federal default. Anything under thirty is not a transition, it is a handover email.
- A transition plan that names a date per division of work. Not “reasonable assistance”. A date against each area of configuration, agreed before you need it.
- Named-personnel continuity, with successor access. The people who made the design decisions are available to explain them to whoever comes next.
- Phase-out costs priced in advance. If exit is unpriced, exit is a negotiation held at your weakest moment.
Write these at signature. A buyer who asks for transition-out terms in month six has told the incumbent exactly what they are thinking, and the price changes accordingly.
There is a systemic version of this failure too. The Committee of Public Accounts, reporting in June 2025 on government’s relationship with digital technology suppliers, found that major digital transformation programmes “have often failed to deliver as intended, with repeated delays and cost overruns, because government has struggled to act as an ‘intelligent customer’.” The scale of the capability gap it documented: 6,000 people with mixed commercial skills across government, against “only 15 digital experts in the centre of government dealing with the largest technical suppliers” — fifteen people covering the nineteen largest technology suppliers, against annual technology spend of at least £14 billion for which there is no central record. The Government Digital Service told the Committee it wanted supplier guidance to cover “how things should work across the lifetime of the relationship, not just up to the point of contracting”, and to address what departments should do when things go wrong, “recognising that no matter how well contracting is done, there are always problems.” That is .
No matter how well contracting is done, there are always problems. The question a contract can answer is not whether problems occur but whether you retain the ability to act when they do.
Why the averages are the wrong thing to plan against
One last piece of evidence, because it reframes what “usually” means in this context.
Flyvbjerg and Budzier analysed 1,471 information-technology projects. The average cost overrun was 27%. That number sounds survivable, and it is the number that gets quoted. Underneath it, “fully one in six of the projects in the sample was a Black Swan, with a cost overrun of 200%, on average, and a schedule overrun of almost 70%.” Their conclusion: “By focusing on averages instead of the more damaging outliers, most managers and consultants have been missing the real risk in doing IT.” The paper is , published in Harvard Business Review in 2011.
One in six. If you run six platform implementations across a decade, the base rate says one of them triples in cost. Your contingency was probably sized against the 27%.
This is also why we do not publish a recovery-cost percentage of our own. A single average would tell you nothing about the case you are actually in, and the distribution is the finding.
How PAteam runs this differently
The five design faults above are all findable before build starts. Our approach is built around making them findable, and around keeping the reset option cheap for as long as possible.
⇒ Design against the exceptions, not the happy path
We start from the contacts that do not behave: the ones spanning two business units, arriving with incomplete records, or requiring a decision no rule covers. Those set the configuration, and the well-behaved contacts fall out as the easy case. This costs more in discovery and less in month eleven, and the mechanism is specific — every exception in the register carries a monthly volume and a named source system, or it is not an exception, it is a category name.
The point is not that exceptions get a phase. It is that a design validated against the awkward twenty per cent of contacts does not need rebuilding when they arrive, because they already arrived, during design.
⇒ Profile the data before the integration design is signed
A share of your customer records is incomplete in ways that will break an agent desktop. That share is knowable in week two and is usually discovered in month nine. We profile it first and design the desktop for what the data actually looks like.
For a US residential construction business, the work that mattered was in the data-entry layer rather than the platform layer — the volume, the field-level completeness, and what the process did when a field was empty. Getting that established up front changed the integration design, which is a much cheaper thing to change than the integration.
⇒ Keep configuration ownership inside your organisation
We name the person on your side who owns configuration after go-live, during design, and we build the change process they will use. A partner who is the only party able to change the system has made the live-fix premium arbitrarily high, which — per the sensitivity above — is precisely the variable that determines whether you have any window at all.
⇒ Report against the original milestone as well as the current plan
Both numbers, every month, exactly as the GAO recommended for the IRS. Progress against the plan as it stands, and progress against the plan as it was when funding was approved. When those two diverge, that divergence is the earliest available signal that a design decision has gone wrong, and it typically appears months before anything else does.
⇒ Honest position: not every failure belongs to the partner
Some of these programmes fail because the buyer could not make decisions at the speed the build required, or changed scope in month seven, or staffed the project team with people who had day jobs. A partner cannot design around an organisation that will not decide. The reason we push the diagnostic work forward is that it surfaces this early enough to matter — if the decisions are not going to be available, that is better established in week three than in month eight, and it changes what should be built rather than who gets blamed.